CyageniCyagen
HomeAI Assistant
Toolbox
Databases
Resources
About Us
AI Tools
RNA Splicer
ASO Designer
Pathogenicity Predictor
Bioinfo Tools
Sequence Viewer
Mutation Direct
Antibody Discovery
Target Insights
Computational Analysis
Databases
Gene Database
Disease Database
Model Database
Mutation Database
Learn
Learning Center
Explore
iCyagen
Cyagen
OriCellTM
AbSeekTM
Contact
Contact Us
EN
中文
About

RNA Splicer is an AI-driven tool developed by Cyagen Biosciences, designed to predict the impact of sequence variants on RNA splicing.

The AI model of RNA Splicer innovatively combines the deep learning DanQ model and the Transformer model, while also integrating the E-value algorithm from bioinformatics.

By training on normal splicing data, this tool can predict potential mRNA splicing alterations following base sequence variants, providing robust technical support for research into the effects of gene variants on RNA splicing.

Mutation information is missing. The system will default to predicting based on absence of mutation. Please confirm to proceed or return to modify.
Home
Tools
RNA Splicer

RNA Splicer

AI-Powered RNA Splicing Prediction Tool

Input
History
About
User Guide
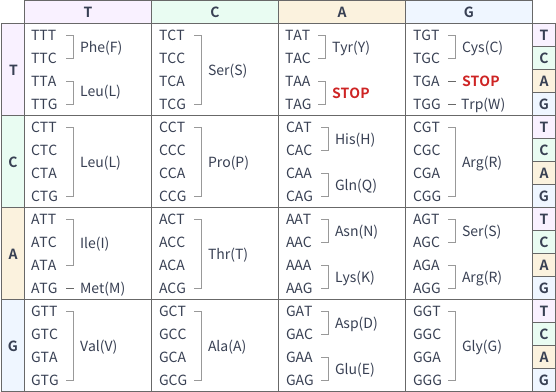
Second base in codon
First base in codon
Last base in codon
Please enter the mutation site in the following input box for prediction.

Codon Chart
01

Input Mode:

?
1. Input mutation: Directly enter or paste standard mutation names.
2. Input transcript: Enter the mutation position and the base after mutation, and the reference base will be automatically filled.
3. Input protein: Enter the mutation position and the amino acid after mutation, and the reference amino acid will be automatically filled.

Standard Mutation Nomenclature:

?
Please enter a standard mutation name that conforms to the HGVS naming rules, for example:
(1)TP53: c.123T>A
(2)TP53: c.123_124TG>C
(3)TP53: c.169+2T>C
(4)TP53: c.45_46insGC
(5)COL4A5: c.36_38del
(6)COL4A5: c.45_47delinsTT
(7)COL4A5: c.-1G>T
(8)DMD: c.*16G>T
(9)DMD: c.23+4_23+5GG>CT
(10)DMD: p.Ser3435Ter
Note: If the system reports an error, it may be due to incorrect name format, failure to comply with HGVS rules, the site exceeding the transcript range, incorrect original base/amino acid, or exceeding the limit on the number of bases or amino acids before and after mutation, among other reasons.

Transcript ID:

?
MANE transcript is the default option. Please make careful to choose the right transcript ID depending on the mutation source, as wrong selection may result in mislocalization. The version number follows the decimal point in the transcript ID. This program uses the most recent NCBI data; using previous versions may not be compatible with this tool and may result in mislocalization.

Reference:

?
After determining the site, the eference base will be automatically filled in without the need for manual input.

Mutant:

?
1. In the case of a mutation, an empty base indicates the deletion of the corresponding base or sequence at the site.
2. Only the abbreviations for the four bases A/T/G/C are allowed, and the sequence length must not exceed 10.
Unfold Diagram
History Record
Update Time
Status
Updater
Review
No data available
0 Results, 10 per Page
Confirm Delete
Are you sure you want to delete ‘--’?
iCyagen
Copyright © 2024 Cyagen Biosciences. All Rights Reserved.
Privacy Policy
User Agreement
Back to top